Modern post-training can involve supervised finetuning (SFT), preference optimisation, RL training using various policy optimisation algorithms and distillation.
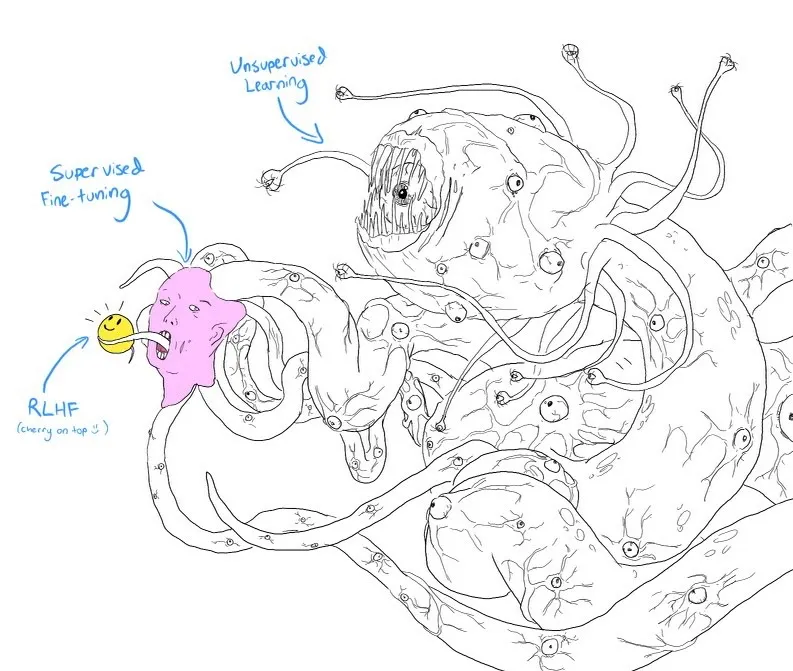
A good analogy I think of different stages is
- Pretraining: Learning language, knowledge and task representations through next-token prediction.
- SFT: Adapting a pretrained model to imitate desired responses, follow instructions and produce task-specific output formats.A
- Preference optimisation: Learn which responses should be preferred over others.
- RL or verifiable RL: It takes one step further, optimizing model behaviour using rewards, preferences or verifiable outcomes rather than only imitating reference responses.
- Distillation: Learn from the behaviour of a stronger teacher model, rather than only from fixed target responses or scalar rewards.
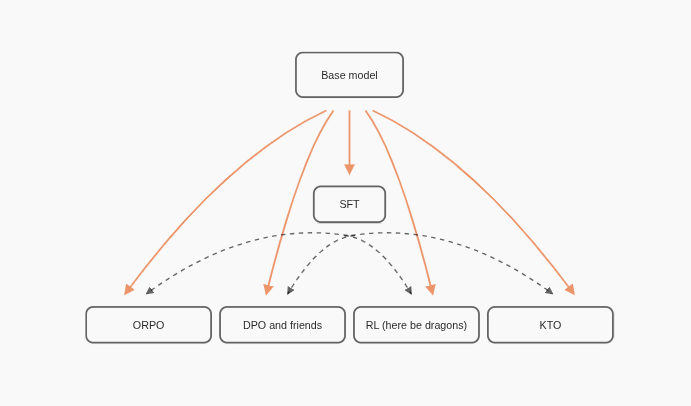
SFT is usually performed after pretraining stage. There’s also a mid-training stage (or continued-pretraining). This stage uses domain-specific dataset to further train the pretrained model before SFT. It is particularly useful when SFT task shares same finetuning domain. SFT models don’t have to learn the core domain specific skills from scratch as pretrained model is warmed up. It is also used for training on large context gradually increasing the context length.
Continued pretraining may be planned in advance when domain adaptation is clearly required, or introduced after early SFT experiments reveal gaps in the base model’s underlying knowledge. If SFT experiment identifies any weak areas for particular task, a targeted mid-training is performed. Mid-training is less useful if base model already has the skill.
A simple way to understand the difference between SFT, RL and on-policy distillation is to ask two questions:
- Who generates the trajectory the student trains on?
- Where does the learning signal come from?
Consider a model learning to answer: Solve: 17 × 13
Supervised Fine-Tuning (SFT): learn from the teacher’s solution
SFT teaches a model by giving it examples to imitate. The training data contains target responses, and the model learns to predict the target response token by token. Training dataset already contains the response that the model should produce. The target may have been written by a human or generated by a stronger model. For example, the dataset could contain either a direct answer: Answer: 221
or a reasoning trace:
17 × 10 = 170
17 × 3 = 51
170 + 51 = 221
Answer: 221
The student is trained with next-token prediction on this fixed response. The teacher generates a trajectory and the student imitates trajectory. Every target token provides supervision. If the teacher writes 51, the training objective increases the student’s probability of producing 51 given the preceding tokens. This makes SFT information-dense and efficient. However, the student trains on states visited by the teacher.
Suppose that at inference time the student instead produces:
17 × 10 = 170
17 × 3 = 41  -> mistake here
The model is now conditioning on a prefix that may never have appeared in the SFT dataset. The teacher would not normally generate the mistake 41, so the student receives little training on how to recover from states created by its own errors. In the terminology used here, SFT is off-policy with respect to the student: the training states come from human or teacher trajectories rather than trajectories sampled from the current student policy.
Reinforcement Learning (RL): learn from the student’s own attempts
In the on-policy RL setting considered here, the student instead generates the training trajectories. The student attempts the problem itself.
Student generates:
17 × 10 = 170
17 × 3 = 41
170 + 41 = 211
Answer: 211
The trajectory is then evaluated: reward = 0. Another rollout might produce: reward = 1 for
17 × 10 = 170
17 × 3 = 51
170 + 51 = 221
Answer: 221
The successful trajectory receives a higher advantage, and the policy-gradient algorithm updates the model so that actions associated with successful trajectories become more likely. The student generates a trajectory, the environment evaluates it and student learns from the reward. In the PPO/GRPO-style RL considered here, training is on-policy: the model learns from trajectories generated by its current or recent policy.
The advantage is that training follows the model into the states it actually visits. As the model improves, it generates new and potentially better training data. The downside is that the reward may contain much less information than an SFT target. If a 2,000-token reasoning trace receives reward = 0, we know that something went wrong, but the reward does not necessarily tell us which token or reasoning step caused the failure. The policy-gradient algorithm still produces token-level gradients, but credit assignment from a trajectory-level reward can be difficult.
Standard RL
A standard RL setup consists of environment, agent, action, policy, state and reward.
- Agent: the system making decisions.
- Environment: the world the agent interacts with.
- State: the current condition of the environment.
- Action: a decision made by the agent.
- Policy: the function used by the agent to choose an action.
- Reward: feedback describing how useful an action or trajectory was.
- Trajectory: a sequence of states and actions produced while interacting with the environment.
At each timestep, the agent observes the current state, samples an action from its policy, and performs that action in the environment. The environment transitions to a new state and returns a reward. The objective is to learn a policy that maximises the expected cumulative reward.
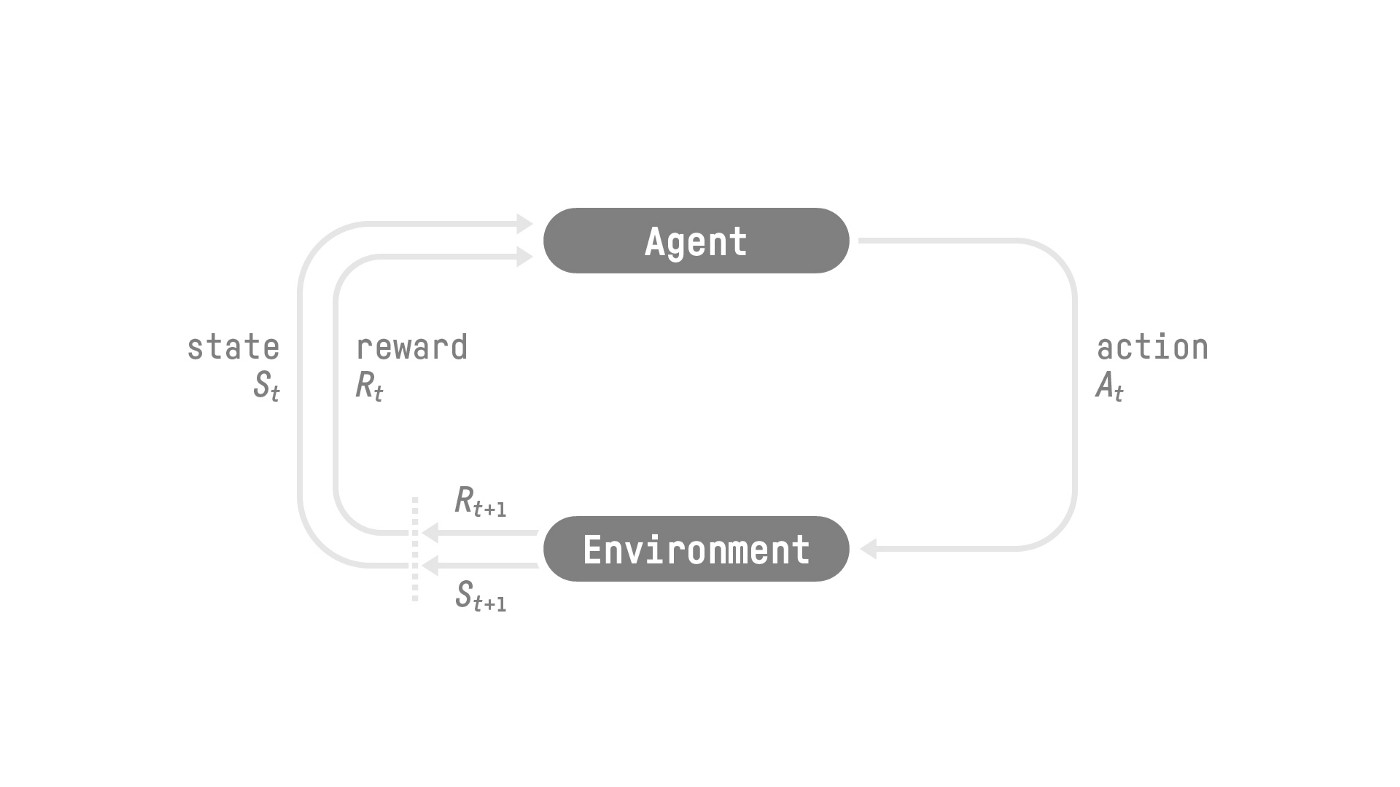
Reinforcement Learning: An Introduction, Richard Sutton and Andrew G. Barto
Language models naturally fit the stochastic formulation because, given some text, the model produces a probability distribution over the next token.
RL for Language Models
In many LLM post-training setups, there is no external environment in the classical sense. There are two useful ways to map the RL formulation onto language generation.
Response level : At response level, the model receives a prompt sampled from the training dataset, generates a completion and receives a reward upon completion. RL components are
- input prompt as the context
- entire completion as the action
- LLM as the policy
- reward as scalar score for the completion
A (prompt, completion) pair is commonly referred to as a rollout or trajectory.
Token level : At token level, generation can instead be viewed as a sequence of state transitions. For example,
state_0 = prompt
action_0 = token_1
state_1 = prompt + token_1
action_1 = token_2
- state becomes input prompt + tokens generated so far
- action will be next generated token
- policy will be probability distribution over the next token
The complete generated sequence forms the trajectory. The interesting difference from supervised learning is that RL does not tell the model which token it should have generated. Instead, the model generates its own trajectory and receives feedback describing how good that trajectory was.
RLHF
Reinforcement Learning from Human Feedback (RLHF) adapts the standard RL setup for finetuning LLM when desired behaviour cannot be expressed as programmatic reward function. There are no simple reward functions that could answer questions like which answer is more helpful? which answer is more creative? or which writing style human would prefer?
RLHF stage following SFT can be broken into two steps:
- Reward Model (RM): Train a reward model using human preference data. The model generates multiple candidate responses and the responses are ranked (or compared) by human annotators. These comparisons are used to train a RM. The reward model learns to predict a scalar value (reward) for a given text on how likely would human prefer the output. A higher value should correspond to a response humans are more likely to prefer.
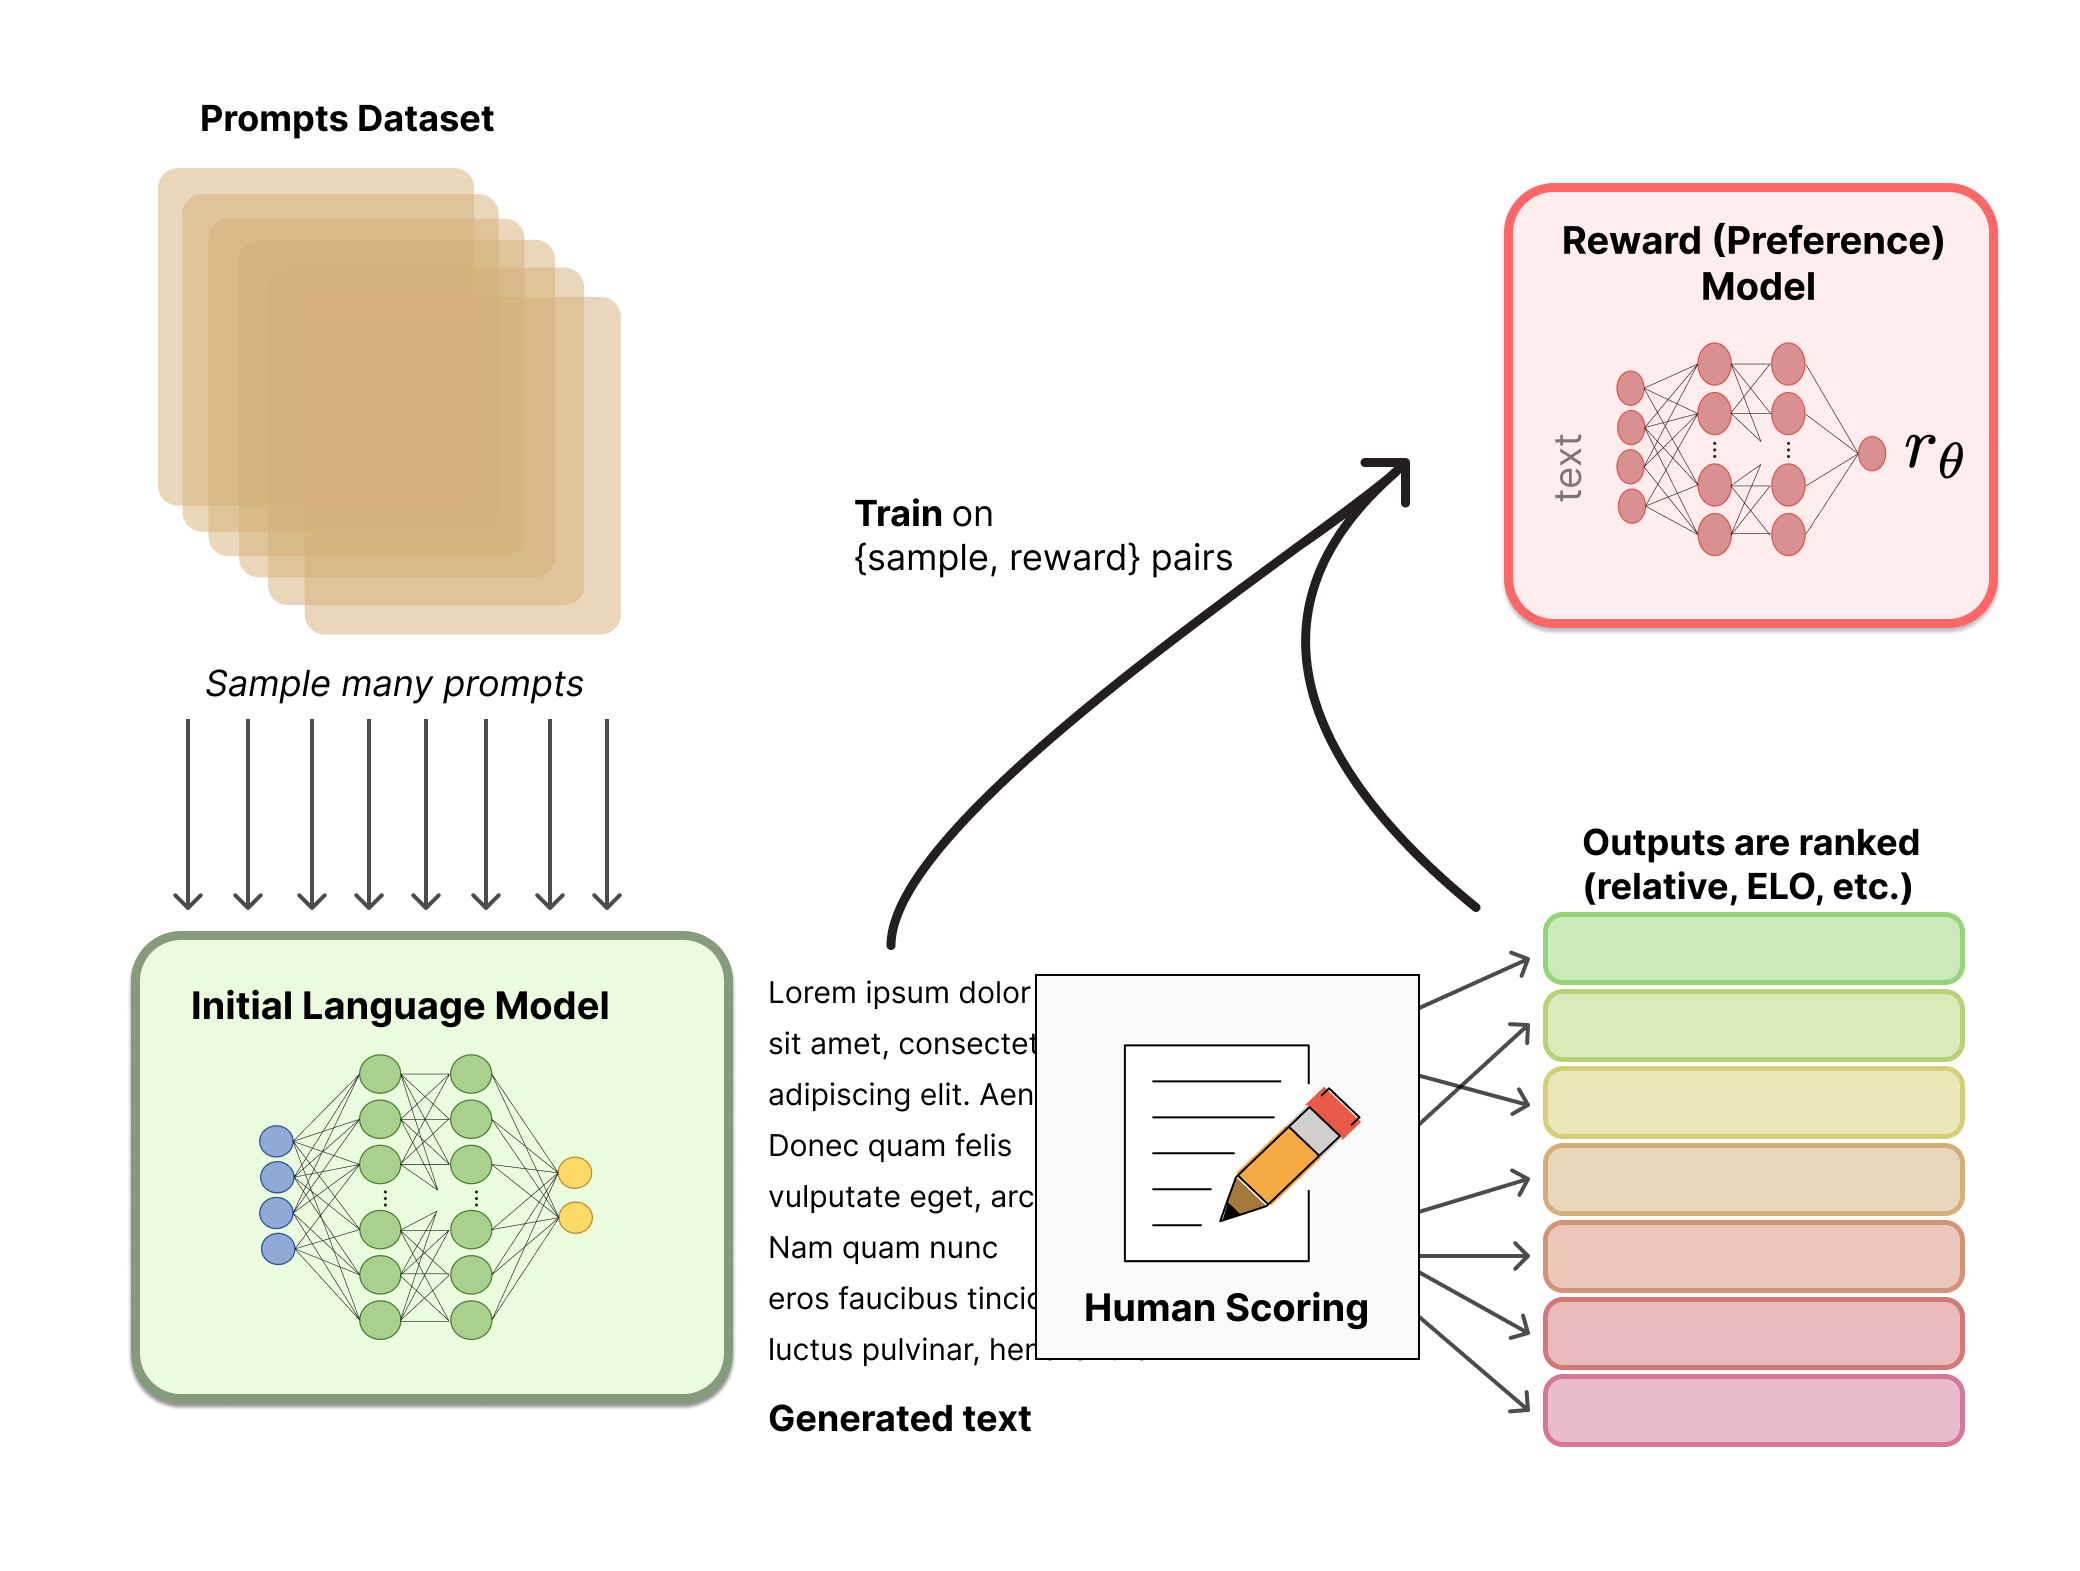
Illustrating Reinforcement Learning from Human Feedback (RLHF)
- Optimising with RL: In this second step, RL is used to optimise the LLM using reward model. The setup consists of initial LLM frozen from SFT stage as reference model. Trainable copy of same model is referred as the policy model. The policy generates responses, the reward model scores them, and policy weights are updated to make high-reward response more likely.
A Kullback–Leibler (KL) divergence term is applied to penalize policy model if it moves away from reference model. Without such a constraint, the policy may exploit weaknesses in the learned reward model rather than genuinely producing better responses.
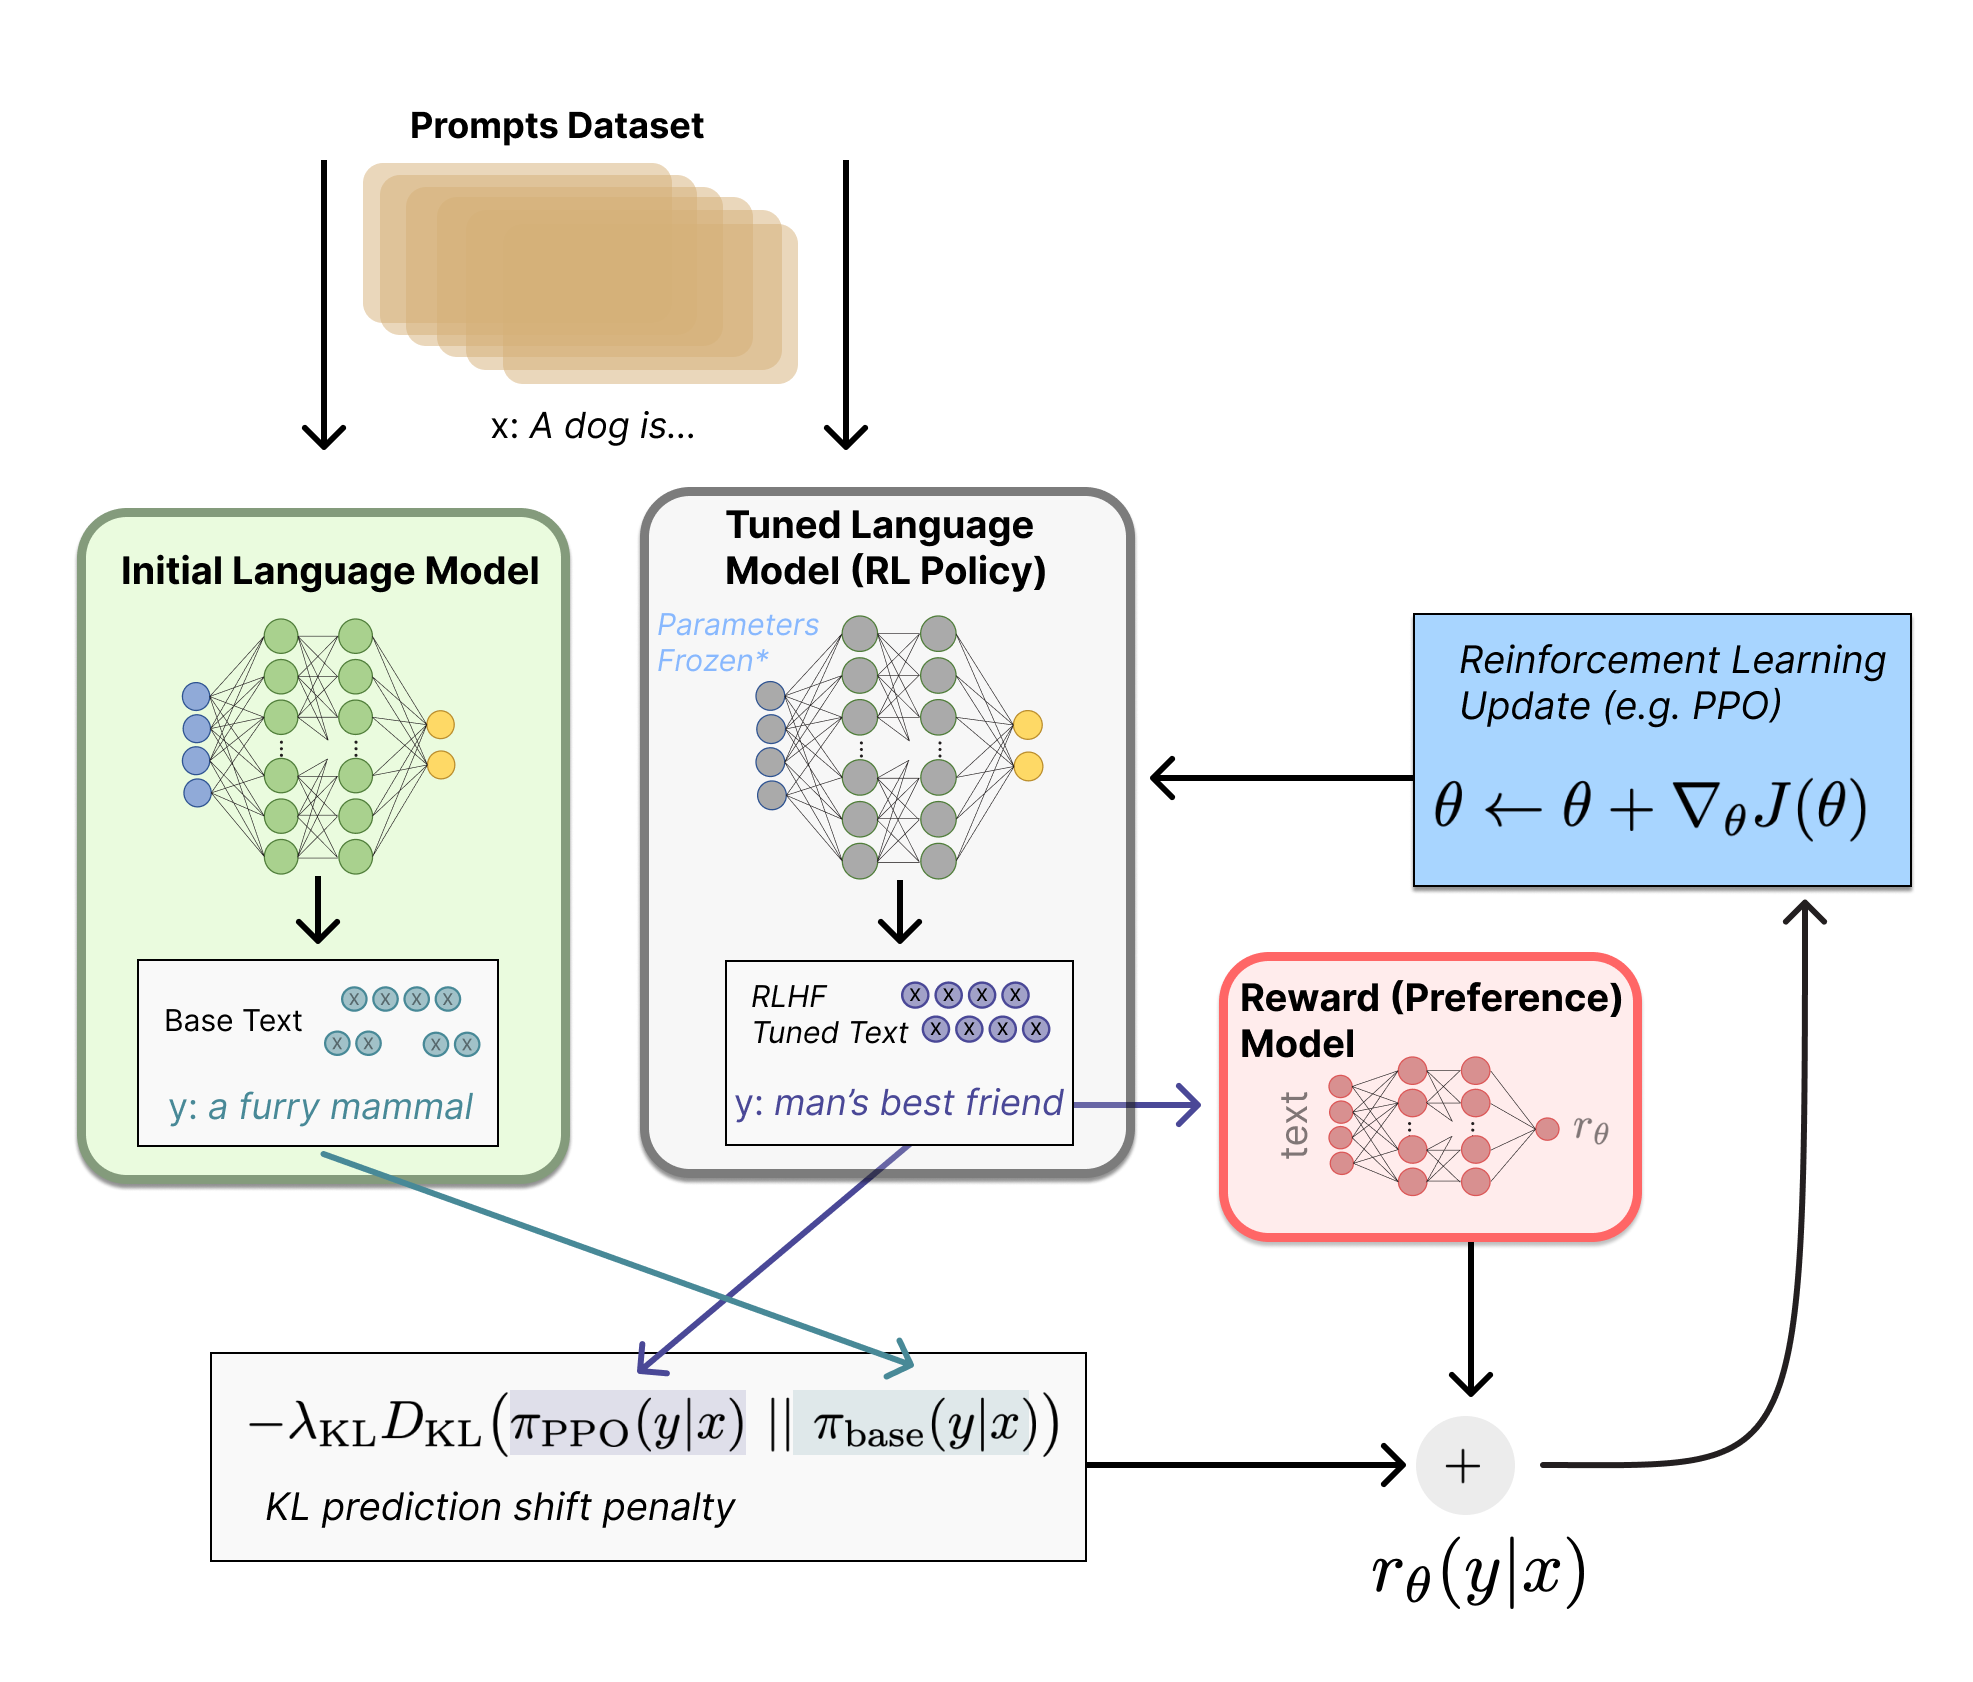
Illustrating Reinforcement Learning from Human Feedback (RLHF)
Policy Gradient Algorithms
The reward tells us whether an output was good or bad, but we still need an algorithm that converts that reward signal into updates to the model weights. This is where policy gradient algorithms such as PPO, GRPO and many other policy optimisation (PO) algorithms come in.
The general idea behind policy gradient to update LLM weights is
- Generate output using the current policy
- Calculate reward
- Estimate an advantage
- Increase probability of good actions or decrease probability of bad actions
The advantage measures how much better or worse a sampled action or trajectory performed compared with some baseline. Different RL algorithms differ in how this baseline is estimated and how aggressively the policy is allowed to change.
PPO uses a learned critic/value model to estimate expected future reward. In LLM PPO, this is typically a transformer with a scalar value head and may be implemented as a separate model or share parameters with the policy. This estimate is then used as a baseline when calculating the advantage. Traditional PPO-based RLHF involves four conceptual model roles: a trainable policy, a trainable value/critic model, a frozen reward model, and a frozen reference policy. The reward model is trained beforehand and the RL stage updates the policy and critic.
Group Relative Policy Optimisation (GRPO), introduced in the DeepSeekMath work, simplifies by removing the need to train a critic model. This frees memory for training. Instead of using a learned value model to estimate the baseline, GRPO generates a group of responses for the same prompt and estimates relative advantage from their rewards.
$$ A_i = \frac{r_i - \mu_r}{\sigma_r}, \qquad \mu_r = \frac{1}{G}\sum_{j=1}^{G} r_j $$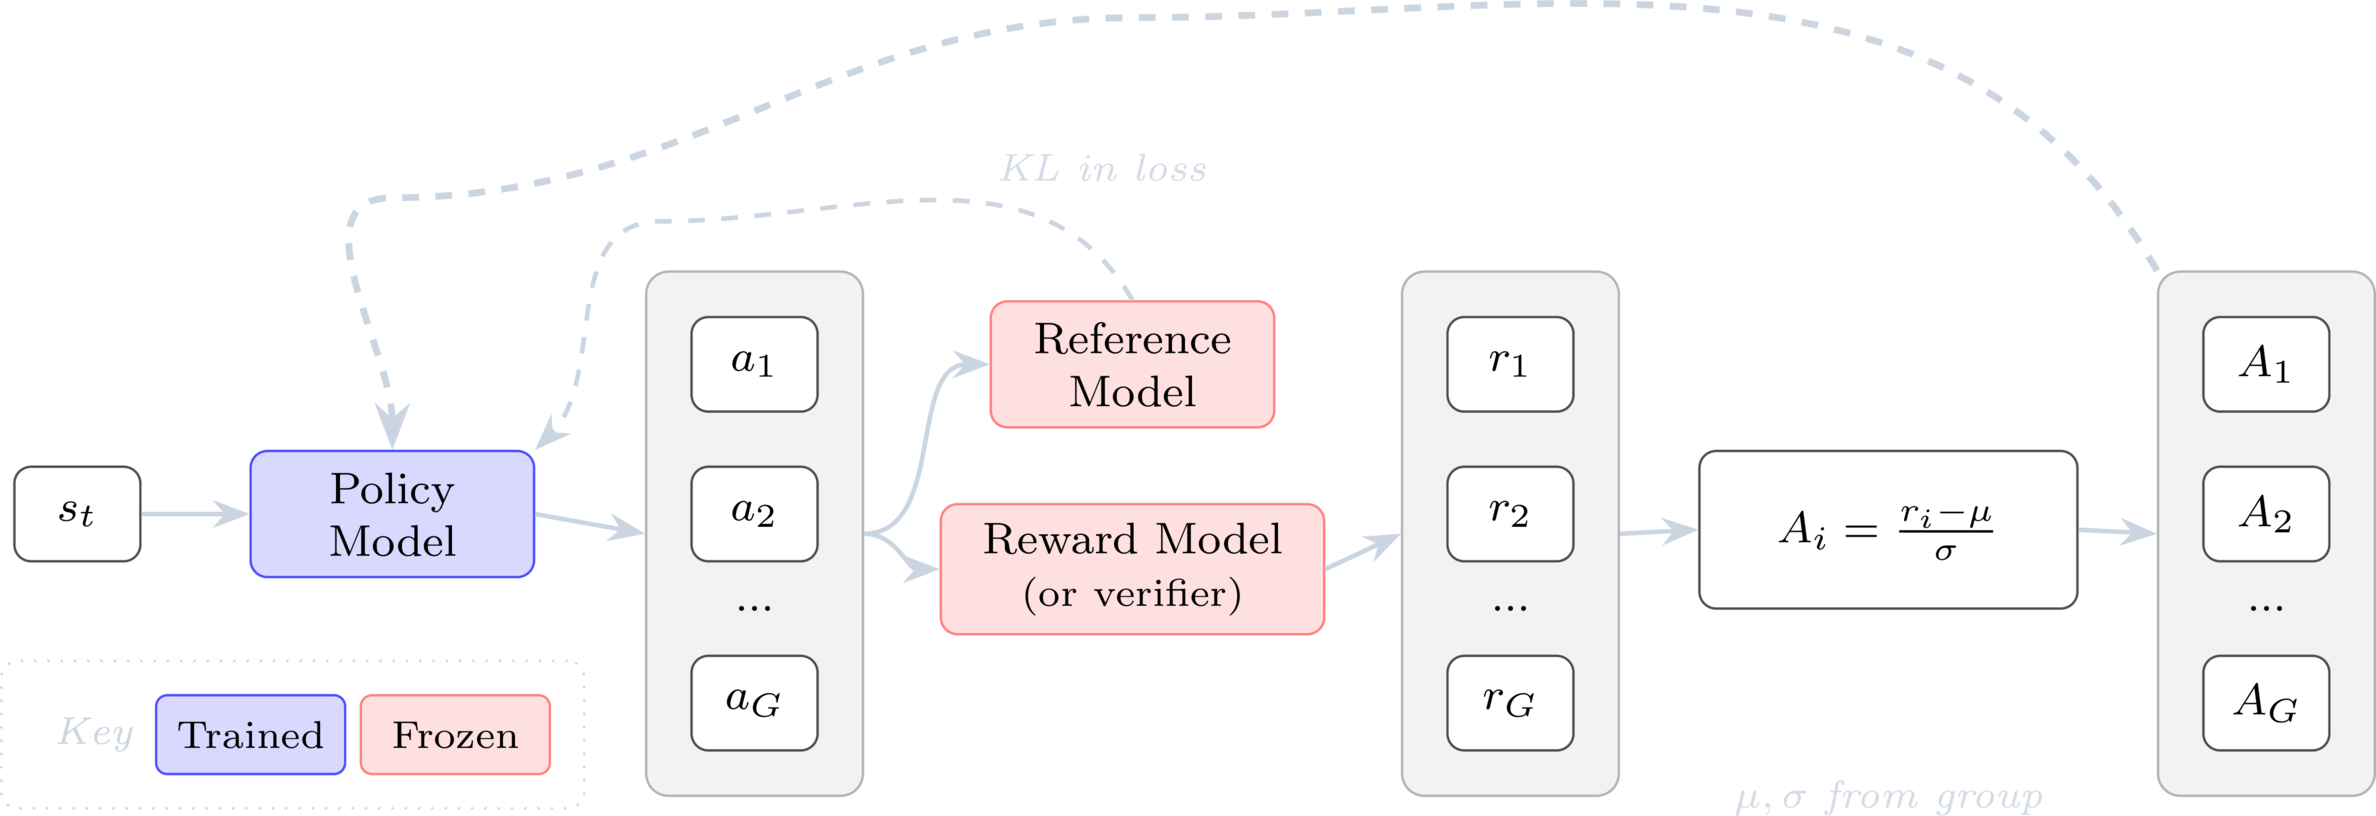
A completion that performs better than the group average receives a positive advantage, while one that performs worse receives a negative advantage. The policy is then updated to make higher-advantage trajectories more likely. One important consequence is that groups where every completion receives the same reward provide no relative learning signal.
For a more detailed comparison of policy-gradient algorithms and their advantage estimators, I recommend the policy gradient chapter of Nathan Lambert’s book.
Reinforcement Learning with verifiable rewards (RLVR)
RLHF is useful when evaluating an answer is subjective. RLVR provides another way to scale RL using verifiable rewards for certain reasoning tasks. The verifiable rewards are functions. For code these functions are unit tests. For maths, these functions are the final expected answer. Instead of learning a reward model from human preferences, RLVR uses a programmatic verifier.
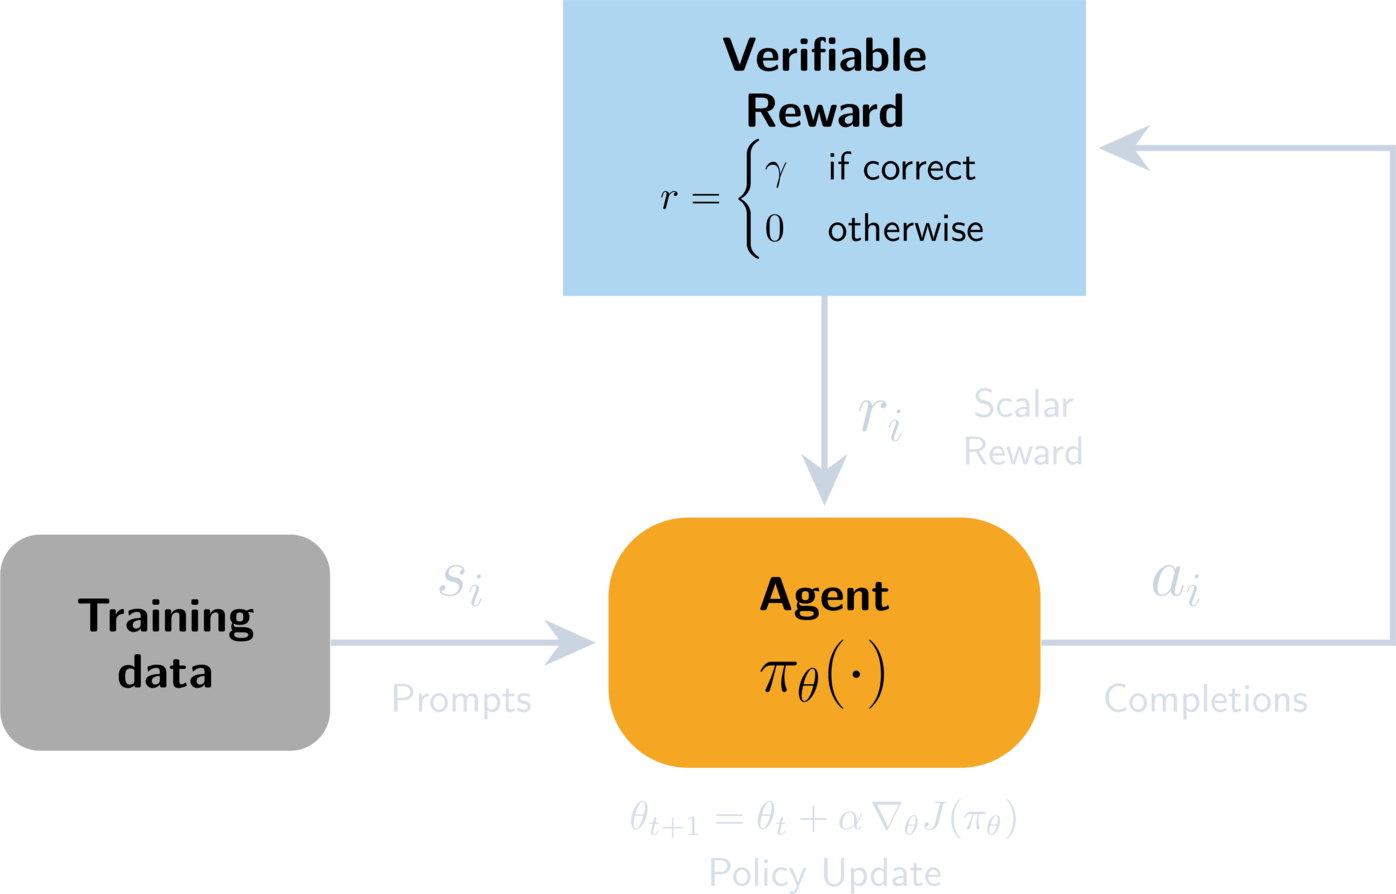
It is a special case of RL where the reward comes from something that can be checked automatically. For this multiplication example, the verifier could simply compare the final answer with the expected answer:
if generated_answer == 221:
  reward = 1
else:
  reward = 0
For code, the verifier could instead execute the generated program against unit tests:
if all_unit_tests_passed == True:
  reward = 1
else:
  reward = 0
The important difference from SFT is that there is no need for a teacher to demonstrate how the problem should be solved. The student is not required to imitate a particular demonstrated solution and can potentially discover alternative successful strategies. The verifier only cares whether the result satisfies the task.
This gives RLVR an interesting property: the student can potentially discover successful behaviours that were never present in a teacher’s demonstrations. Its weakness is still the sparsity of the learning signal. A final pass/fail result tells the model whether a trajectory worked, but often not where it went wrong.
In agentic RLVR training setup, RL environments play a significant role in scaling the RLVR training. RL environments provide the external state, tools, observations and execution context needed to evaluate or continue a trajectory. For code RLVR, the policy may generate code on a rollout server while a sandbox environment executes that code against tests and returns the resulting reward.
A paper from DeepSeek showcased insane engineering behind DeepSeek Elastic Compute platform that supports serving 3 million sandboxes per day in production. It can create 5000 sandboxes per second and running over 380,000 of these concurrently.
Preference optimisation
Direct Preference Optimisation (DPO) provides another way to train from preference data without explicitly training a reward model and then using reinforcement learning to optimise against it. A DPO dataset contains a prompt together with a chosen response and a rejected response. The preference may come from human annotators, another model or some other ranking process.
For example:
Prompt:
Solve: 17 × 13

Chosen:
17 × 10 = 170
17 × 3 = 51
170 + 51 = 221
Answer: 221

Rejected:
17 × 10 = 170
17 × 3 = 41
170 + 41 = 211
Answer: 211
Instead of learning a scalar reward model that assigns the chosen response a higher reward and then running PPO or another policy-gradient algorithm, DPO directly updates the policy so that the chosen response becomes more likely relative to the rejected response.
The reference policy is a frozen copy of the model before DPO training. For each chosen/rejected pair, DPO compares how much the trainable model prefers the chosen response over the rejected one with how much the original model preferred the same pair. Training pushes this preference further toward the chosen response. The training signal comes from being told which of two responses is preferred, rather than from a single target response as in SFT or a scalar reward as in RL.
DPO is normally an offline method: the chosen and rejected responses already exist in the preference dataset rather than being generated by the current policy during each training step. This also means that, unlike the on-policy PPO/GRPO setup considered above, the policy does not continually explore new trajectories as it changes.
The attraction of DPO is its simplicity. Preference optimisation can be implemented much more like ordinary supervised training: there is no separately trained reward model, no rollout generation during training and no policy-gradient RL loop. The trade-off is that the model is learning from the preference pairs contained in the fixed dataset and is therefore limited by the states and behaviours represented in that data.
On-policy distillation: let the student drive, but let the teacher correct it
On-policy distillation combines aspects of SFT and RL. Like the on-policy RL setup above, the student generates its own trajectory. Suppose the student produces:
17 × 10 = 170
17 × 3 = 41
Instead of only receiving: reward = 0 a stronger teacher model evaluates the student’s actual prefix.
At:
17 × 3 =
the distributions might look like:
Student:
P(41) = 0.65
P(51) = 0.10

Teacher:
P(41) = 0.001
P(51) = 0.97
The teacher therefore provides a strong learning signal precisely at the state where the student’s behaviour diverged. The student first generates its own trajectory. The teacher produces its token distribution at each student-visited state, and the distillation objective pushes the student’s distribution toward the teacher’s.
This is also on-policy, because the states being trained on came from the student. But unlike RLVR, the feedback is dense. Instead of receiving one scalar reward for the whole trajectory, the student can receive information at every generated token.
Analogy
A useful analogy is:
SFT: Watch an expert solve the problem and imitate them.
RLVR: Solve the problem yourself and only check whether the final answer is correct.
DPO: Look at two completed solutions and learn which one should be preferred.
On-policy distillation: Solve the problem yourself while an expert watches each step and tells you how they would act from the exact state you reached.
Inspired by Will Brown’s post on comparing SFT, RL and OPD and Thinking Machine’s blog on On-Policy Distilattion.